GCP Committed Use Discounts for GKE Clusters
Match the commitment to your billing model, then rightsize first.
GCP committed use discounts for GKE clusters work best when the commitment follows the billing model and a rightsized workload baseline. Resource-based CUDs reward stable Standard node capacity, while Compute Flexible CUDs cover eligible spend across changing resources and services. Choosing between them depends on cluster mode, workload predictability, and term length. The central rule is to optimize first, then commit to the capacity or spend that remains.
Why GKE billing splits into two fundamentally different commitment models
GKE Standard bills for node pools made of Compute Engine VMs. The bill reflects allocated VM capacity whether pods use it or not, so a resource-based commitment can attach to vCPUs, memory, a machine family, and a region. GKE Autopilot instead bills for the CPU, memory, and ephemeral storage that pods request, while Google manages the underlying nodes. There is no machine-type surface to commit against. Google's CUD documentation therefore routes eligible Autopilot usage exclusively to the Flex model.
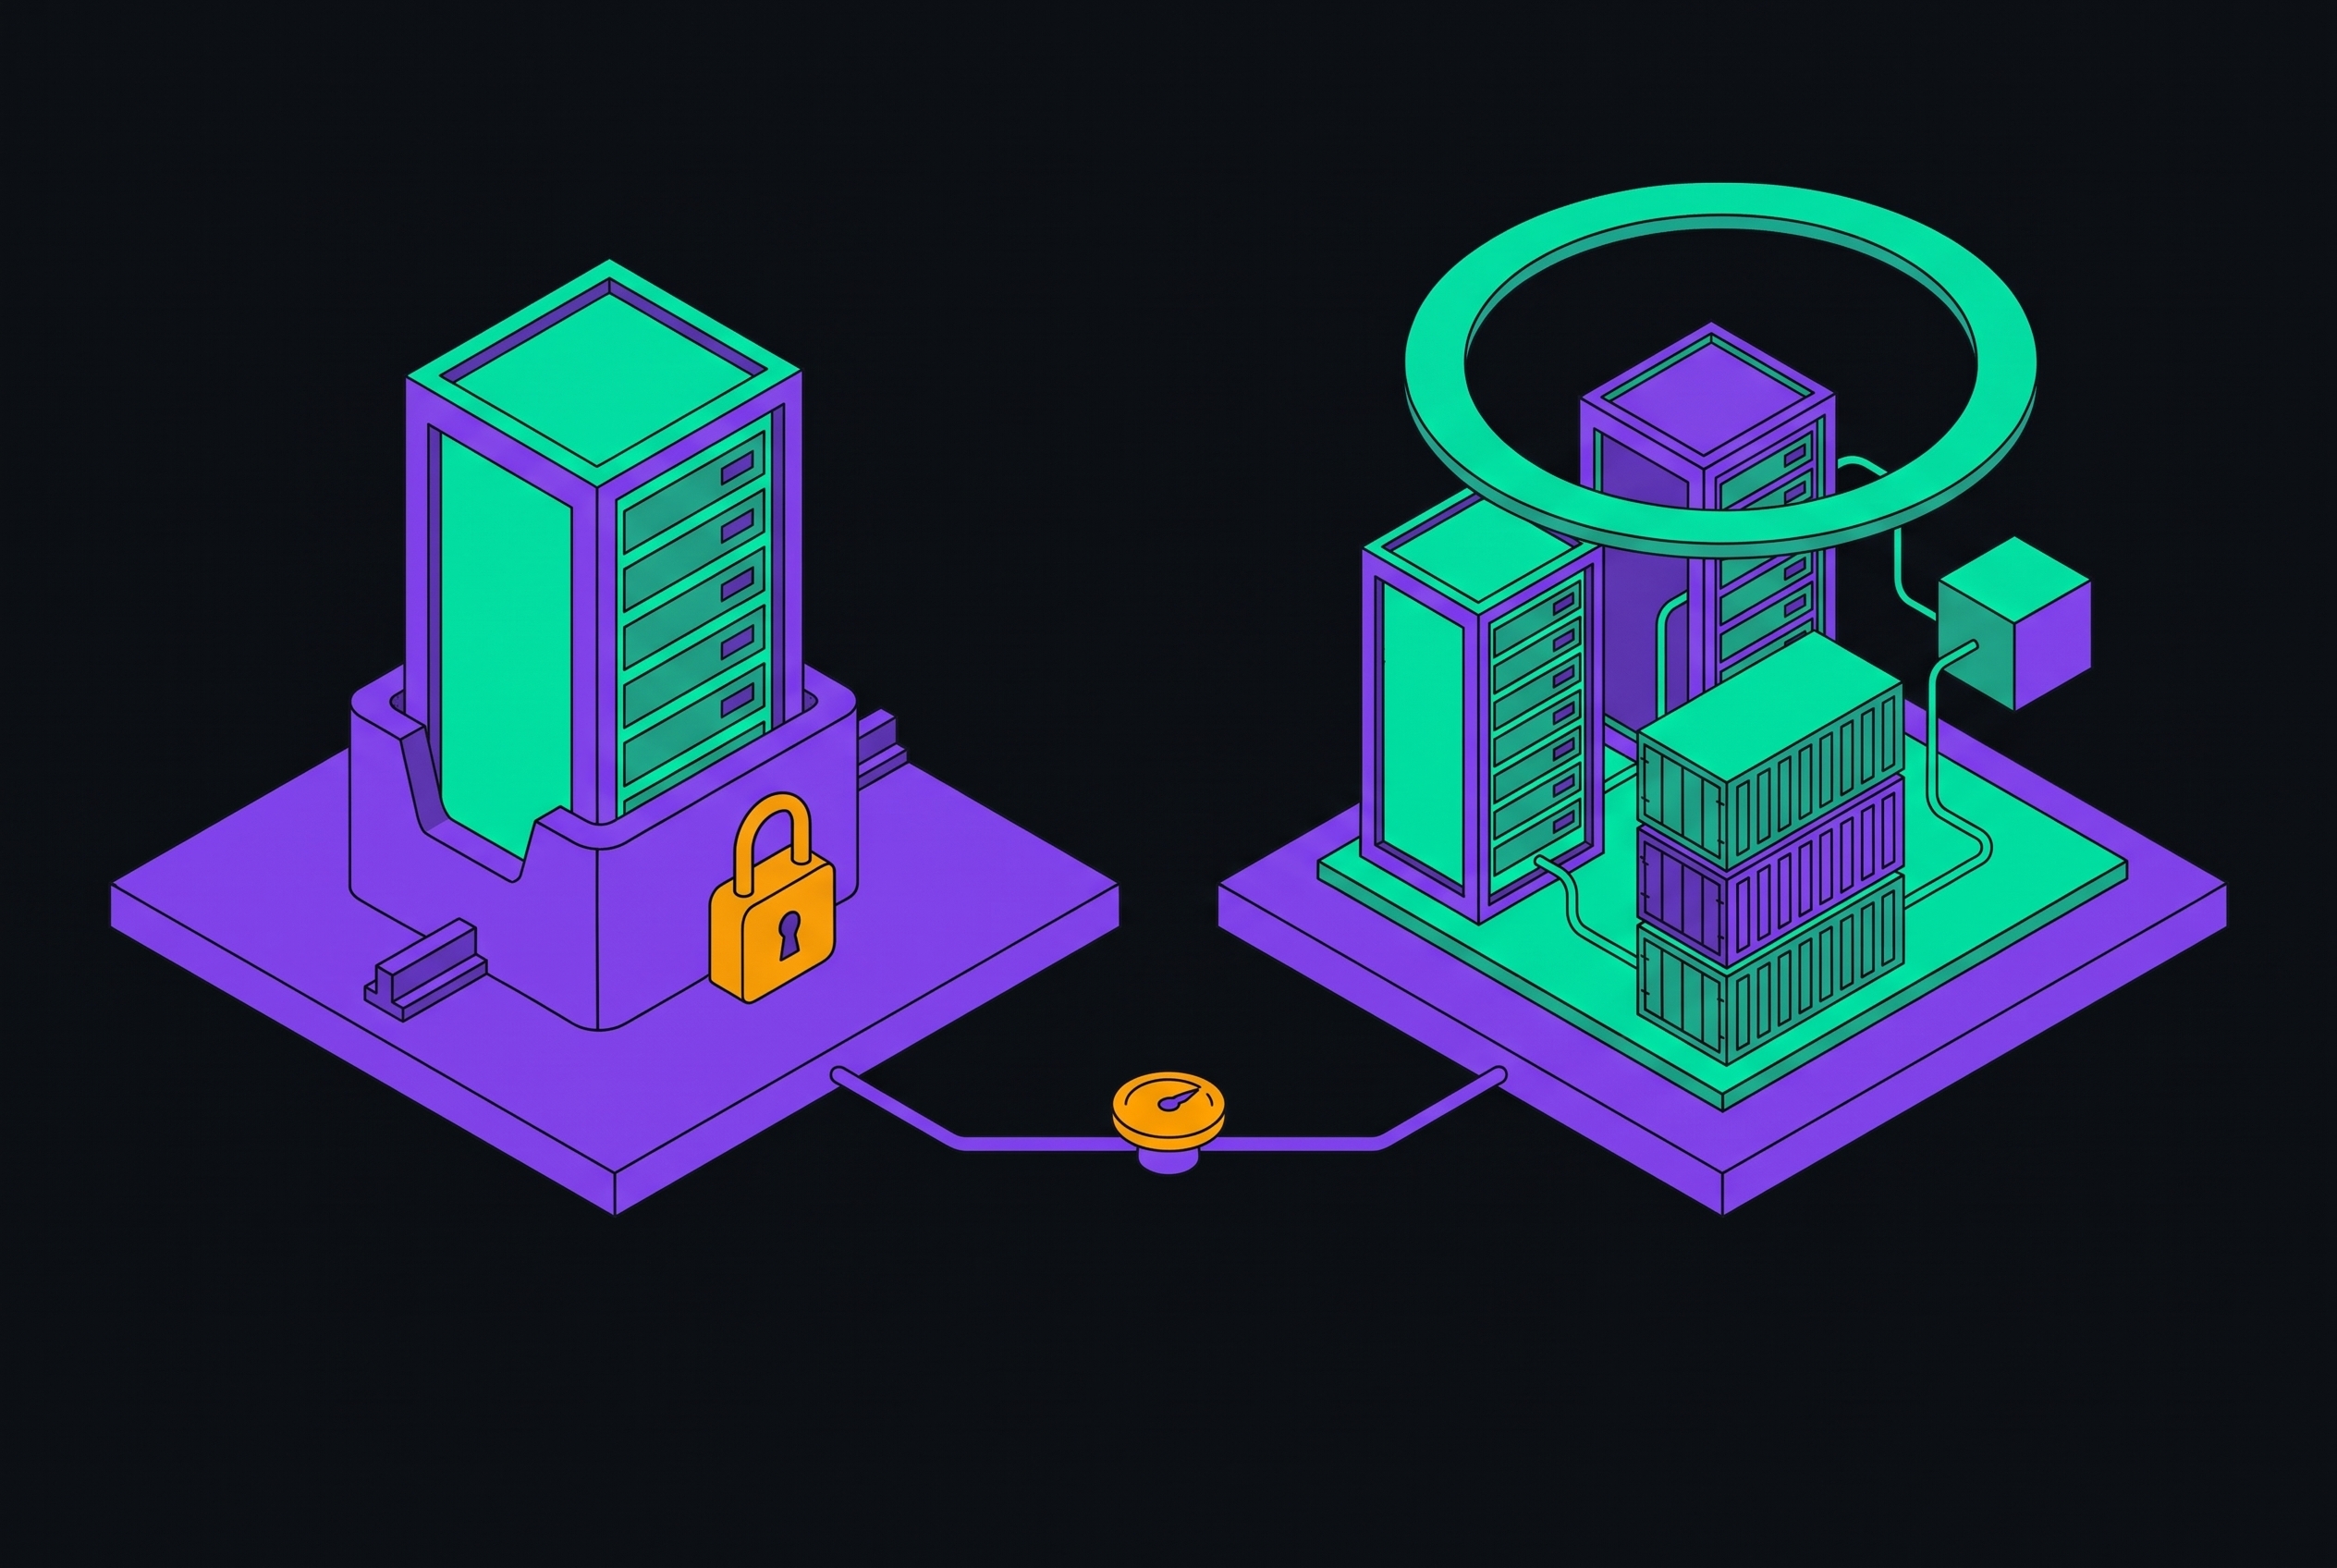
That distinction makes cluster mode the first decision gate. Resource-based CUDs tie a commitment to specific resources in a region, while Flex CUDs tie it to a minimum hourly spend on eligible Compute Engine, GKE, and Cloud Run usage. Standard can use either path, but Autopilot cannot. Both have one-year and three-year terms. The difference is what must remain predictable throughout that term, namely the resource configuration or the eligible spend.
What the January 2026 Autopilot shift to Flex CUDs actually changed
Autopilot-specific CUDs are no longer available for new purchases. Google Cloud now uses Compute Flexible CUDs for new commitments for eligible Autopilot usage, so plans to buy the former product need to change. Flex is a commitment option for both GKE modes. It does not, however, give Autopilot access to the deeper resource-based discounts available to eligible Standard workloads.
Google's spend-based CUD documentation dates the billing-model transition to January 21, 2026. The new consumption-model format shows discounted rates directly rather than calculating usage at list price and offsetting it with a credit. This changes reporting while leaving rates unchanged. Total cost is not supposed to increase because of the transition, but dashboards built around the previous format can misrepresent savings unless their calculations change.
FinOps dashboards and cost allocation tooling that expect list-price charges plus CUD credits need to use the new consumption-model format. Teams that bought Autopilot commitments before January 2026 should also check how those commitments are being handled. New purchases follow the Flex path regardless of how an earlier commitment was classified.
How resource-based CUDs work for GKE Standard node pools
Resource-based CUDs let Standard users commit to vCPUs and memory within a machine series and region, with discounts up to 55% for general-purpose families. The commitment is tied to those resource choices. Moving to a different machine type or region mid-term does not transfer it, so a planned migration can weaken an otherwise attractive purchase. A three-year term therefore calls for confidence in the resource configuration over a longer period than a one-year term.
Google's Compute Engine CUD documentation identifies eligible resources beyond vCPUs and memory, including GPUs, local SSDs, sole-tenant nodes, OS licenses, and block storage resources called Hyperdisk Exapools. Eligibility does not make every resource interchangeable within a commitment. When planning a node pool, the boundary is still the resource type, machine series, and region covered by the commitment. The discount should be evaluated against the capacity the workload can use within that boundary.
Billing-account scope also affects how much eligible usage a commitment can cover. Google's documentation states that all Cloud Billing accounts created on or after June 16, 2026 have CUD sharing enabled by default. Resource-based commitments then automatically cover eligible usage in projects that share the same billing account. Teams with older accounts should check how their scope is set.
The savings comparison needs equal care because Sustained Use Discounts do not stack with CUDs. Eligible Standard node VMs can receive SUDs automatically, but usage covered by a CUD does not also receive a SUD. The correct comparison is against the SUD-discounted cost already being paid. E2 is the brief exception to this calculation. E2 machine types earn no SUD, so there is no existing SUD benefit to subtract from the CUD savings.
How Flex CUDs work and when they fit better than resource-based CUDs for Standard clusters
Flex CUDs exchange minimum hourly spend for discounts without locking the commitment to a machine type or region. Their headline discounts are lower than those of resource-based CUDs, but their coverage is broader. A single Flex commitment can cover eligible Standard node compute, Autopilot pod billing, and Cloud Run usage. Resource-based commitments cannot span those services. Google's documentation describes Flex as a fit when spend is predictable but the underlying resources may change.
For a Standard cluster, the first practical question is whether its machine family and region will remain stable for the full term. If both stay the same, there is a stronger case for resource-based CUDs, especially when the commitment does not need to cover other services. Memory-optimized workloads sharpen that distinction. Their resource-based discounts can reach up to 70%, a depth not available through Flex. That benefit depends on retaining eligible usage rather than migrating away from the committed resources.
Multiple machine families, an anticipated machine-type migration, or coexisting Standard and Autopilot clusters can favor Flex. Cloud Run spend that stays predictable is another reason to consider it. A final question is whether one unified commitment is operationally simpler enough to justify the lower headline discount. The choice turns on what the team can predict.
Why the Cluster Autoscaler creates a sizing trap that invalidates naive CUD baselines
Choosing a commitment type does not establish how much to buy. Most Standard clusters run with the Cluster Autoscaler enabled, so node counts change while the commitment remains fixed. A purchase based on average or peak node count becomes underutilized when the cluster scales down. The average blends periods of sustained demand with capacity that the workload only needs intermittently.
Pod requests can distort that baseline further because the autoscaler provisions against requested resources. Oversized requests make the cluster appear to need more nodes than the workload requires. A fixed commitment can then turn an inflated configuration into a contractual obligation. For Autopilot, the equivalent error is sizing a Flex spend floor from oversized pod requests. Correcting those requests after purchase can push eligible spend below the committed minimum.
Commit against the minimum usage held consistently. A conservative approach covers only part of that baseline and leaves the remainder on pay-as-you-go pricing or automatic SUDs where eligible. For Standard, the node pool minimum can then be set to the number of nodes covered by the CUD. This keeps the autoscaler from scaling below the capacity covered by the commitment. It keeps the commitment consumed, but it does not prove that the retained nodes are necessary. Rightsizing must therefore precede that setting.
Why rightsizing pod requests must come before any commitment purchase
Rightsizing changes both the quantity that should be committed and the efficiency of using it. Oversized pod requests tell the autoscaler that demand is higher than it is, leading to a node count that is later mistaken for a stable baseline. Purchasing against that count discounts unnecessary capacity for one to three years. The lower rate makes the original sizing error harder to correct without leaving part of the commitment unused.
The recommended sequence is to measure actual pod usage, rightsize requests, measure the new stable baseline, and only then size and purchase the commitment. Each stage supplies the evidence needed by the next. Consumption data supports request changes, while the resulting node count or hourly spend establishes the commitment floor. Measuring only before rightsizing misses the effect of the optimization. A baseline suitable for purchase must describe the workload after requests have been corrected.
This order is especially direct in Autopilot because pod requests determine the bill. A Flex commitment calibrated to oversized pod specifications can become excessive as soon as those specifications are reduced. Standard introduces the additional step of translating requests into provisioned nodes, but the sequencing requirement is the same.
Rightsizing also needs to continue after the first purchase. New deployments, configuration drift, and incident-driven over-provisioning can erode the gains and raise spend above the committed level. Later reductions can move spend in the opposite direction. These changes justify baseline reviews during the term and before renewal, rather than treating the purchase as the end of optimization.
How Standard versus Autopilot mode affects the total cost picture when CUDs are applied
Once the workload has been rightsized, commitment options can change the cost comparison between Standard and Autopilot. At low node utilization, Autopilot tends to cost less because the team does not pay for idle node capacity. At high utilization, well-applied resource-based CUDs can make Standard meaningfully cheaper for the same workload. The crossover depends on pod placement efficiency. Tight bin-packing lets Standard use more of the VM capacity it pays for.
Large, well-tuned Standard clusters can use their nodes well and get resource-based rates, including the deeper discounts for memory-optimized families. Autopilot must use Flex, which does not offer those rates. Idle Standard capacity can offset the advantage of the discount.
Autopilot also transfers node provisioning, upgrades, and bin-packing to Google. Having less to manage helps, especially for teams that have no dedicated platform engineering staff. Teams that cannot or will not invest in bin-packing optimization generally do better on Autopilot regardless of discounts. The mode decision therefore depends on both utilization and operational capacity. Commitment depth is one part of that calculation.
A practical decision workflow for choosing and sizing CUDs on GKE
The purchasing workflow should begin by establishing cluster mode in the GKE configuration. For Autopilot, evaluate Flex only and skip resource-based commitments. For Standard, retain both options until workload stability and cross-service needs are clear. This first gate narrows the purchase path. It prevents time spent comparing discounts that cannot apply to the workload.
Next, use data on what pods actually consume to change resource requests before measuring the commitment baseline. Measure the resulting stable floor with P10 usage data rather than averages, using node count for resource-based planning or eligible hourly spend for Flex. The baseline must reflect the rightsized configuration.
For Standard, choose resource-based CUDs when the machine family and region are stable and cross-service coverage is unnecessary, with particular attention to memory-optimized workloads. Choose Flex when machine types may change, Autopilot or Cloud Run coexist under the billing account, or a unified commitment is worth the lower headline discount. Then select a one-year or three-year term against the expected period of stability.
Size the purchase to the floor rather than the average, and consider covering only part of it. Leave the remainder on on-demand pricing or SUDs for eligible Standard VM families. For resource-based Standard commitments, set the node pool minimum to the number of nodes covered by the commitment. For Autopilot Flex commitments, use the spend floor produced by rightsized requests. Check how CUD sharing is set up in the billing account before counting on coverage across projects.
Before purchasing Flex, update dashboards and allocation tooling that still expect list-price charges plus credits. Use the new consumption-model format so that reported savings reflect the billing structure. Schedule a baseline review before renewal and after significant workload changes. Automated continuous rightsizing can reduce request drift between those reviews. The renewal decision should follow the workload's current baseline.
Sources
- Committed use discounts (CUDs) for Compute Engine | Google Cloud Documentation
Supplied the details on resource-based and Flex CUD eligibility, discount ceilings, terms, billing-account sharing, and SUD interaction.
- Google Kubernetes Engine pricing
Underpins the explanation of how GKE Standard bills for node VMs while Autopilot bills for pod resource requests.
- About GKE cluster autoscaling | Google Kubernetes Engine (GKE) | Google Cloud Documentation
Supports the point that the autoscaler provisions nodes against pod requests, so node counts shift while commitments stay fixed.